
Voice AI agent architecture refers to the design of the software agent that enables it to listen to human voice, interpret its meaning and respond in natural language. Most production systems are composed of three layers: speech-to-text, language model, and text-to-speech, and are connected as a chained pipeline, one speech-to-speech model, or one unified API. This is why many teams are now investing time in the selection of the appropriate voice AI agent architecture before coming up with the first line of code: the cost reduction of contact center labor will be $80 billion by 2026 in the age of conversational AI. This guide explains the inner workings of the pipeline, what it does when someone calls an AI agent, and what you should do to ensure you have a setup that is suitable for what you’re building.
What Is Voice AI Agent Architecture?
The voice AI agent architecture is the skeleton that links three jobs: listening, thinking, talking. The system listens to the person, transcribes text, a language model analyzes the intent, determines the response, and outputs audio. Each voice AI agent architecture, regardless of how it’s branded, is simply the different wiring of these three jobs.
The difference between a good and a mediocre voice AI agent architecture is not the most flashy model in the stack, rather it’s how tightly the pieces are connected, and how quickly the information flows between them. When an AI agent is on a bad phone line, it’s when a handoff occurs between listening and thinking. How Do AI Voice Agents Work Under the Hood?
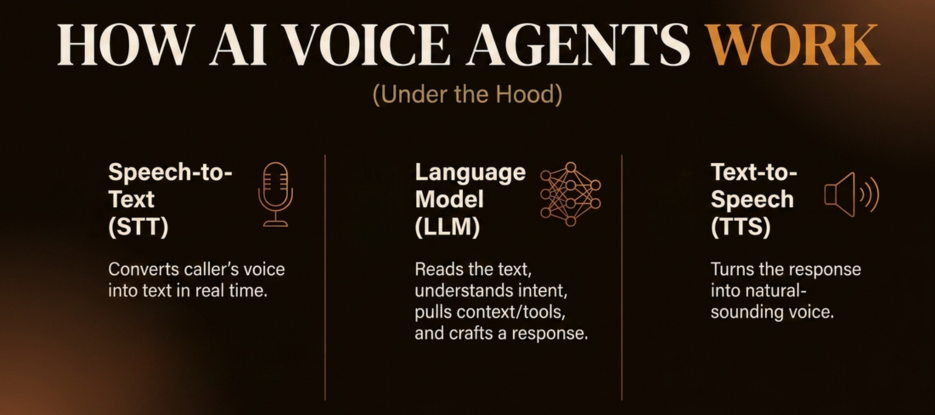
So how do AI voice agents work in practice? Most are based on three parts that are linked in sequence:
- Speech-to-text (STT): Transforms the caller’s voice into text, as it is spoken. The key to any voice AI agent architecture is getting the transcriptions right, because everything downstream responds to an incorrect question when the transcriptions are incorrect.
- Language model (LLM): Takes in the transcript, understands the intent, accesses context and/or tools as necessary, and generates a response.
- Text-to-sound (TTS): Transforms things that respond back to natural-sounding sound.
Here, speed is a must. Rather, modern systems are more sophisticated and depend on a neural end-of-turn detection system, as people don’t intentionally stop talking in the middle of their speech. A quality voice AI agent architecture will be able to listen to pacing and tonality rather than silence to determine when someone stops speaking.
What Happens When You Call an AI Agent?
It is helpful to go through the flow of calling an AI agent, as it will explain why the architecture of voice AIs is important:
- When you begin talking, the audio comes in through the system in little bits and pieces, instead of waiting until you have completed your sentence.
- It is transcribed live by the STT layer to generate partial results in a few hundred milliseconds.
- The turn detection system makes sure you’re done speaking, not just when you fall silent.
- The language model analyzes the transcript, verifies the intent, and accesses any other tools required such as order lookup for an AI voice agent for ecommerce deployment.
- The speech is generated by the TTS engine, and the voices are returned to you.
- The loop is repeated on each turn in the conversation, ideally taking about 1 sec for the whole round trip.
So if one part of that chain is slow, or fails, the caller knows it right away. That’s why it’s so popular with engineering teams: voice AI agent architecture is not a theoretical exercise, it’s the difference between a natural conversation and talking to a broken IVR.
What Are the Core Components of a Voice AI Agent Pipeline?
A complete voice AI agent pipeline typically consists of:
- Ingestion and streaming: recording and broadcasting the caller’s voice without any noticeable lag or delay in between.
- Automatic speech recognition (ASR/STT): converting speech to text with high accuracy of names, numbers, and domain-specific terms
- Natural language understanding (NLU): Understanding the context, entities, and intent of the conversation in the transcript
- Dialogue management / orchestration: what to do next (including tool calls, escalation logic, etc)
- Text-to-speech synthesis: generating a natural-sounding voice response
- Turn-taking and interruption handling: managing when to speak, when to listen, and when to stop mid-sentence if the caller interrupts
These can be built, purchased or bundled, and that is indeed what makes up your voice AI agent architecture. Teams that view this as housekeeping – “put it together, put it out” – often find themselves having to do this again when real call volume forces them to discover the cracks.
What Does a Modern Voice AI Tech Stack Look Like?
The typical voice AI tech stack in 2026 cThis becomes especially important for a multilingual AI voice agent handling multiple languages in real time (typically through an API gateway to allow flexibility in choosing and using the LLM), a TTS provider, and an orchestration layer in charge of turn taking, tool calls and session state. Many modern LLMs classify intents natively, but some teams have a separate NLU layer for intent classification.
The orchestration layer is a topic that needs to be looked at more than is typically done. It’s the component of the voice AI tech stack that determines when to interrupt, what to do if something in the tool call fails, and when to pass a customer over to a human agent. A good voice AI agent design is one that sees orchestration as a first-class citizen, instead of an add-on tacked at the end.
Under all of that is telephony integration (SIP trunking, WebRTC, or platforms such as Twilio), which links the actual telephony network to the pipeline. It’s easy to ignore until latency on that layer begins to consume your response time budget.
What Are the Different Voice AI Agent Architecture Models?
To date, there are three predominant patterns in use, and choosing which one to use is the biggest decision in any voice AI agent architecture project.
Cascading (Chained STT → LLM → TTS)
This is the traditional model: an individual model for each stage of the process linked together in sequence. It provides 100% control, so you can switch STT providers, switch LLM, and update voice separately; it also provides you with a readable transcript at each stage, which is important for debugging, compliance, and quality audits. The cost of integration overhead: 3 vendors, 3 latency budgets, 3 places something can fail.
Speech-to-Speech (End-to-End)
The multimodal model accepts input as audio and outputs as audio, rather than relying on an intermediate and visible textual component. It is easier to stand up and can reduce latency since there are no handoffs, but it can’t be as useful for visibility of the transcript as it can be for the fine-grained control of entity accuracy or to swap out any one component without replacing the entire model.
Unified API (Managed Pipeline)
This model operates a cascading pipeline behind a single connection; while the outside appears to be a simple one, it acts just like the flexible approach below. Three separate vendors? Nope, you get one bill, one set of logs, and still visible transcripts without having to integrate them yourself. This has been the preferred method for teams that don’t need to acquire all the layers and are looking for production-grade accuracy. And much of the reason for the rapid adoption of unified voice AI agent architecture in the last year.
How Does an AI Voice Agent Work in Real-Time Conversations?
Understanding how does an AI voice agent works in live conversations goes beyond its individual parts; it’s about how the AI agent functions as a whole in the context of live dialogue. A truly natural-sounding system must:
- Tolerate and deal with interruptions well (don’t finish a line if someone cuts in)
- Understand the difference between a pause and a completed turn- the neural turn-detection problem, yet again, and one of the most difficult aspects of any voice AI agent architecture to get right
- Maintain context across turns (not requesting a name or account number that has already been provided)
- Communicate with precision: email addresses, dates, dollar amounts, and confirmation numbers, where just one misheard digit spoils the whole thing!
This is where the ball’s accuracy is compounded by the STT layer. It isn’t just transcribing a podcast for someone to edit afterwards – it’s a live decision that is made in real time, and a misplaced word makes all the difference.
Why Does Voice AI Agent Architecture Determine Accuracy and ROI?
The architecture you pick will put a limit on what your agent is able to accomplish, since there’s nothing that can correct an error done upstream. The speech-to-text layer fails to hear the account number for a particular reason, and the language model goes off and does something based on the incorrect account number; the reason was correct, but the input was not.
This is why when choosing voice AI agent architecture options, entity accuracy (or the ability to accurately recognize names, numbers, and identifiers) is more important than general transcription accuracy. It is possible for a system to have a low overall error rate, but to be consistently failing on the exact details that are most important in a transactional call. Teams that miss this evaluation phase end up finding out the hard way once they’re in deployment, when escalation rate doesn’t fall as anticipated by the pilot.
How Do You Choose the Right Voice AI Agent Architecture for Your Business?
While there is no universally “best” voice AI agent architecture, there is a “best” fit based on the use case, team size, and willingness to own infrastructure.
- If you’re a larger team developing a very differentiated product, and want to have complete control over every stage, you should choose cascading.
- Use speech-to-speech when you’re creating, say, a casual, conversational prototype and precision of transactions isn’t as important.
- If you’re looking for production-level accuracy and control without having to integrate and maintain three different vendors, you’ll want to choose a unified API; that’s where most teams that bring their first serious voice product to market are landing.
Regardless of your decision, practice authentic accents and with background noise and messy speech before putting it to the test with actual customers. A demo environment isn’t like a Monday morning call queue.
What Are Common Mistakes in Voice AI Agent Architecture Design?
Some patterns repeatedly emerge in projects that stall or fail to perform:
- Rather than seeing STT as a layer some layers down from everyone else, treating it as an interchangeable commodity.
- No turn detection tuning – leaving the agent speaking over callers or causing awkward pauses
- Supporting a wide “do anything” use case as opposed to a narrow, measurable workflow
- Not following the path of escalation towards a human, which destroys trust as soon as the agent reaches its limits
- Failure to simulate the noise and accent conditions before go-live.
Most of these are not architecture faults per se but simply choosing a voice AI agent architecture without testing the assumptions that went into it.
Conclusion
Voice AI agent architecture isn’t a background implementation detail; it’s the decision that determines whether your agent sounds sharp or sloppy on a live call. Whether you choose a chained pipeline, a speech-to-speech model, or a unified API, the same principle holds: the system can only be as good as its weakest link, and that’s usually the listening step. Get the foundation right, test it against real conversations, and the rest of the experience follows. If you’re planning your next voice AI build, it’s worth mapping your use case against these architecture patterns before you commit to a stack. Talk to a voice AI specialist to find the right fit for your team.
Frequently Asked Questions
What is voice AI agent architecture?
The system design that links speech-to-text, a language model, and text-to-speech to enable a voice agent to listen and reply to spoken conversation. Typical patterns are cascading pipelines, speech-to-speech models, and unified APIs.
How do AI voice agents work in real time?
Audio streams in, is transcribed in real time, and interpreted by a language model, which then generates a response, which is then converted back to speech. Neural turn detection ensures an end-to-end exchange of about 1 second.
What happens when you call an AI agent?
Your voice is transcribed immediately, a language model understands your request, it brings out all the information it needs, and a text-to-speech engine answers you back in a loop lasting about a second per turn.
Which voice AI agent architecture is best for a new product?
It depends on the control requirement. Unified APIs are for most first-time builders looking for accuracy without vendor complexity; cascading APIs are for teams that require comprehensive customization; speech-to-speech is for basic, common use scenarios.