
The technology that uses machine learning to convert spoken audio into written text is called Automatic Speech Recognition (ASR). Today’s automatic speech recognition (ASR) systems use deep neural networks to address accents, background noise, and dozens of languages – both live and recorded. This guide discusses how ASR works, ASR word error rate (WER) explained in layman’s terms, the best ASR models compared for 2026, end-to-end ASR vs hybrid ASR, ASR accuracy vs latency trade-offs, and choosing an ASR engine for enterprise use. Whether you’re creating a voice agent, a call analytics tool, or a transcription workflow, these trade-offs will keep you from the hassle of costly surprises.
What Is Automatic Speech Recognition and How Does It Work?
Core Definition of Automatic Speech Recognition
In other words, it’s like a sound wave that’s converted into text. It hears the audio, infers the words spoken, and provides text that software can search, summarize, or analyze.
Why Automatic Speech Recognition Demand Keeps Growing
The market is growing rapidly: The global speech and voice recognition market was worth $4.2 billion in 2016 and will reach $23.70 billion by 2026, according to the report, and will hit $104.05 billion by 2034. Speech recognition, meeting transcription, translation for dictation, and contact centers all rely on accurate text from chaotic speech.
The Five Stages of an Automatic Speech Recognition Pipeline
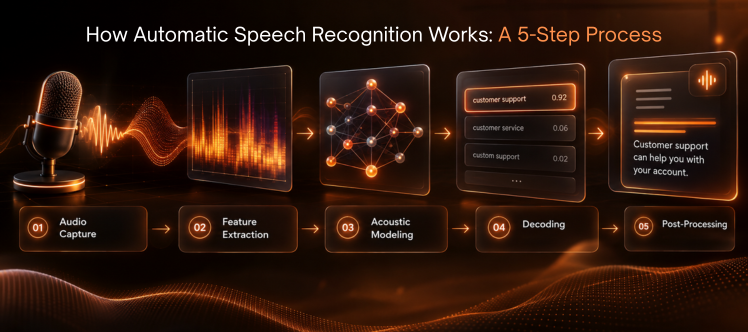
Most automatic speech recognition pipelines follow the same basic path:
- Audio capture: System records (or streams) the sound, typically 16kHz.
- Feature extraction: A technique that reduces the waveform to a “smaller” representation, typically a log-mel spectrogram.
- Acoustic modeling: A neural network guesses what speech sounds or word parts are in the speech.
- Decoding: The most probable word sequence is selected.
- Post-processing: Punctuation, capitalization, number formatting, and speaker labels are added.
These steps were utilized as individual components in older systems. Most of them are incorporated into a single network, which we will see later in newer automatic speech recognition models.
How Is Accuracy Measured? ASR Word Error Rate (WER) Explained
In automatic speech recognition, WER is the standard yardstick. It compares a model’s transcript with a human-made reference and counts three kinds of mistakes: substitutions (S), deletions (D), and insertions (I). The formula is simple: WER = (S + D + I) ÷ number of words in the reference.
Here’s a quick example. If the reference has 100 words and the model gets 4 wrong, drops 2, and adds 1, the WER is 7%. Lower is better.
Limits of Word Error Rate
Before you trust any single number, keep three cautions in mind:
- Every word counts equally. Missing “the” costs the same as missing a drug name.
- Text normalization moves scores. How a scorer handles numbers, casing, and punctuation can shift results noticeably.
- Clean-audio WER rarely predicts real-world WER. Your call recordings will look worse.
Beyond WER: Entity Error Rate
That’s why many teams also track entity error rate. Names, amounts, and account numbers usually carry the real business value. Keep this in mind whenever you see ASR word error rate (WER) explained in a vendor’s marketing: a low average can hide costly mistakes on the words that matter most.
Key takeaway: WER is a useful screening number, not a verdict. Always pair it with tests on your own audio.
What Is the Difference Between End-to-End ASR vs Hybrid Models?
How Hybrid ASR Systems Work
Hybrid automatic speech recognition systems split the job into parts: an acoustic model, a pronunciation lexicon, and a language model, joined by a decoder. Kaldi-style pipelines are the classic example. Each part can be tuned on its own, so hybrid designs are easier to customize for niche vocabulary and easier to audit.
How End-to-End ASR Systems Work
End-to-end systems train one network to map audio straight to text. The main families are CTC, transducer (RNN-T), and attention-based encoder-decoder models. Whisper is an encoder-decoder design. A newer wave, including Qwen3-ASR and IBM Granite Speech, bolts a speech encoder onto a text language model. That approach is cheaper to train, but it can cost more and run slower at inference.
End-to-End ASR vs Hybrid Models at a Glance
| Factor | Hybrid | End-to-end |
| Structure | Separate acoustic, lexicon, and language models | One neural network |
| Customization | Simple vocabulary additions | Needs fine-tuning or prompting |
| Open-benchmark accuracy | Usually trails | Leads current leaderboards |
| Engineering effort | Higher | Lower |
While most new research in automatic speech recognition is end-to-end, older enterprise applications are using hybrid pipelines. The choice between end-to-end ASR vs hybrid models typically depends on the desired control over vocabulary versus engineering time invested.
What Are the Best ASR Models Compared Side by Side in 2026?
Open ASR leader board Snapshot
This is a “snapshot” of automatic speech recognition leader boards, which are changing rapidly. The table is based on the Hugging Face Open ASR leader board published on 26/03/2026. This is a composite average of WER on eight English test sets, and a better score is lower.
| Model | Average WER | Type |
| Cohere Transcribe | 5.42 | Open weights, 14 languages |
| IBM Granite 4.0 1B Speech | 5.52 | Open, compact |
| NVIDIA Canary Qwen 2.5B | 5.63 | Open, LLM-based |
| Qwen3-ASR-1.7B | 5.76 | Open, LLM-based |
| ElevenLabs Scribe v2 | 5.83 | Commercial API |
| OpenAI Whisper Large v3 | 7.44 | Open, broad language support |
The board has kept shifting since, so check the live version before you commit. Any honest list of the best ASR models compared this year comes with the same caveat: rankings depend heavily on which test sets you pick.
Commercial ASR APIs Worth Testing
Commercial automatic speech recognition APIs deserve a look too. Deepgram, AssemblyAI, and ElevenLabs compete hard on streaming, while Google, AWS, and Azure stay practical if your data already lives there. One warning: vendor-published benchmarks tend to flatter the vendor. Favor independent tests such as Artificial Analysis, and always run your own audio through a shortlist drawn from the best ASR models compared above.
How Do ASR Accuracy vs Latency Trade-Offs Work in Real Time?
Batch vs Streaming Accuracy
Every automatic speech recognition system trades accuracy against speed, and batch transcription sits at one end. It can look at the whole recording, so it usually wins on accuracy. Streaming automatic speech recognition has to commit to words before the speaker finishes, and that costs precision. One academic comparison found streaming APIs produced noticeably higher error rates than batch mode.
What the Streaming Benchmark Numbers Show
Actual numbers show the tension. On the AA-WER Streaming benchmark from Artificial Analysis, ElevenLabs Scribe v2 real-time reached 3.65% WER at about 0.13 seconds. Deepgram Flux was the fastest at roughly 0.02 seconds, but it posted 7.36% WER. Those results are ASR accuracy vs latency trade-offs in action.
Latency Budgets for Automatic Speech Recognition by Use Case
Which side should you favor? It depends on the job:
- Voice agents: latency dominates. The entire speech-to-text, language model, and text-to-speech must be kept at approximately 800 milliseconds.
- Live captions: a slight lag of 1-3 seconds is okay.
- Meeting notes and call QA: record afterwards and accept the accuracy.
Engine tuning is now possible, too, for some engines. Transitions also support the ability to predict or modify chunk settings during inference with NVIDIA’s cache-aware Nemotron streaming model, and AssemblyAI comes with three latency modes.
Key takeaway: Determine the length of time you can tolerate first and then select the most accurately modeled system that is within that time frame.
Which ASR Benchmarks and Datasets Should You Trust?
Common ASR Benchmarks and Datasets
Public datasets give automatic speech recognition teams a common ruler, though each one measures something different:
- LibriSpeech: read audiobooks. Clean and easy, so scores look great.
- Common Voice and FLEURS: read speech across many languages, popular for coverage tests.
- TED-LIUM: prepared talks with one speaker at a time.
- AMI: real meetings with overlapping voices.
- Earnings-22 and SPGISpeech: financial calls, heavy on jargon and numbers.
- VoxPopuli and GigaSpeech: parliamentary recordings and mixed web audio.
Why Benchmark Scores Can Mislead
The catch is that clean read-speech sets only show a best-case picture. Production audio with overlap, music, and poor microphones pushes error rates up. Contamination is another worry, since a model that saw test data during training will look better than it is. Use ASR benchmarks and datasets to build a shortlist, then create a private test set from your own recordings.
Key takeaway: A strong automatic speech recognition benchmark score is a shortlist filter, not a purchase decision.
Which Multilingual ASR Models Handle Global Audio Best?
Language Coverage Across Leading Multilingual ASR Models
The languages supported with automatic speech recognition are extremely diverse. OpenAI’s Whisper was the obvious multilingual choice for years and was available to translate into 99 languages. Meta’s Omnilingual ASR supports over 1,600 languages, including approximately 500 that were not previously supported by any ASR system, and character error rates of less than 10% for 78% of languages. Cohere’s Transcribe is not about broad coverage but about focusing on 14 enterprise languages. For businesses, AssemblyAI’s main real-time model supports 18 languages and code-switching in the middle of a sentence.
Dialects and Code-Switching
It’s not coverage, however. Multilingual ASR models fail in dialects. In June 2026, Whisper Large v3 achieved a 36.86 WER compared to a 25.87 WER for a Cohere model trained on a specific Arabic dialect on the Open Universal Arabic ASR leaderboard. If your customers use Egyptian, Gulf or Levantine Arabic, a general model might not be enough. Also test code-switching, like Hindi with English, as many models require one language per clip.
What ASR Model Training Data Requirements Should You Plan For?
Data Scale Behind Leading Automatic Speech Recognition Models
Whisper learned from roughly 680,000 hours of labeled audio. Cohere’s 2026 model used about 0.5 million hours of curated audio-transcript pairs, then added synthetic data after error analysis. Those numbers describe building from scratch, which few enterprises need to do.
Practices That Reduce ASR Model Training Data Requirements
For most teams, the real question in automatic speech recognition projects is adaptation, not pretraining. ASR model training data requirements shrink a lot when you focus on the right things:
- In-domain audio: recordings that match your microphones, accents, and jargon.
- Accurate transcripts: clean labels beat sheer volume. Noisy labels teach bad habits.
- Noise augmentation: Cohere mixed in background noise at signal-to-noise ratios from 0 to 30 dB.
- Speaker diversity: a spread of ages, regions, and speaking styles.
Training for Low-Resource Languages
Low-resource languages are the exception. Among the languages where Meta’s system reached a CER below 10%, 195 were trained on under 10 hours of data. Self-supervised pretraining can stretch small datasets a long way.
Key takeaway: For automatic speech recognition, data quality and domain match usually beat raw data volume.
How Should You Approach Choosing an ASR Engine for Enterprise Use?
Checklist for Choosing an ASR Engine for Enterprise Use
Choosing an automatic speech recognition engine is different from picking a demo. Start with your constraints, then narrow the list:
- Test on your own audio. A few hours of representative recordings will tell you more than any leaderboard.
- Measure beyond WER. Check entity accuracy, punctuation, and speaker labeling.
- Match latency to the use case. Streaming for agents, batch for analytics.
- Decide where it runs. Cloud API, private cloud, or on-premises for regulated data.
- Review security and compliance. Look at data retention, encryption, and certifications such as HIPAA, GDPR, and SOC 2.
- Check customization. Custom vocabularies and fine-tuning matter for product names and technical terms.
- Watch for hallucinations. Some encoder-decoder models will transcribe silence or noise, so pair them with voice activity detection.
Running a Pilot Before You Commit
Run a short pilot with two or three automatic speech recognition engines before signing anything. Model quality is rarely the only reason enterprise projects stall. Integration, data handling, and monitoring matter just as much, and automatic speech recognition works best when it’s treated as part of a wider data pipeline.
Bottom Line
Automatic speech recognition has transitioned from a problem to a component of a practical system. Modern models can achieve average WERs around 5% on public English tests, respond in sub-second time on streaming engines, and support more than a thousand languages in open models. However, no leaderboard can give you any idea of how your model will perform on your accents, your jargon, and your phone lines. Shortlist to benchmark, then make your own decision. If an organization views the technology of automatic speech recognition not as a one-off investment, but as an ongoing process or evaluation exercise, it will detect accuracy degradation early and adjust faster to new models. Do small increments, measure the performance truthfully, and scale accordingly.
What Questions Do People Ask About Automatic Speech Recognition?
What is automatic speech recognition used for?
Voice assistants, live captions, meeting transcription, call center analytics, clinical dictation, and voice agents are powered by automatic speech recognition technology, which converts spoken words into searchable text, on-the-fly or later.
How accurate is automatic speech recognition?
Today, the top models achieve an average of 5% WER on public benchmarks on clean English audio. Typically, the quality of a real-world call audio is better, and 10% or below is regarded as excellent for production.
What is the difference between automatic speech recognition and speech-to-text?
Automatic speech recognition (ASR) and speech-to-text are synonymous. The underlying technology is called ASR, and the finished product, or the function, is called speech-to-text, which refers to the conversion of spoken sounds into clean written words.
How does automatic speech recognition work?
It takes audio and turns it into features, goes through a neural network that can guess what sounds are in the person’s speech or what word pieces are, translates that most likely word sequence, and adds punctuation and formatting.